A-Z of AI in Healthcare
Training

Want to see how this training process extends to more advanced, agentic AI systems?
What is AI training?
The word "training" refers to the process of teaching an algorithm how to do its job, for example, how to classify images (telling the difference between a normal scan and an abnormal scan), or how to predict whether a person is at risk of developing a particular disease. It's largely a process of repetitive trial and error.
How does this compare to teaching a child?
Think of teaching a child to recognise colours. You might show them a stack of cards, each a different primary colour, saying "blue" every time a blue card appears, "red" for a red card, and so on. Over time, the child learns to label each card correctly without help, and eventually applies that knowledge to new objects, like correctly naming the colour of a mug, even without a card present.
How does this play out when training an algorithm?
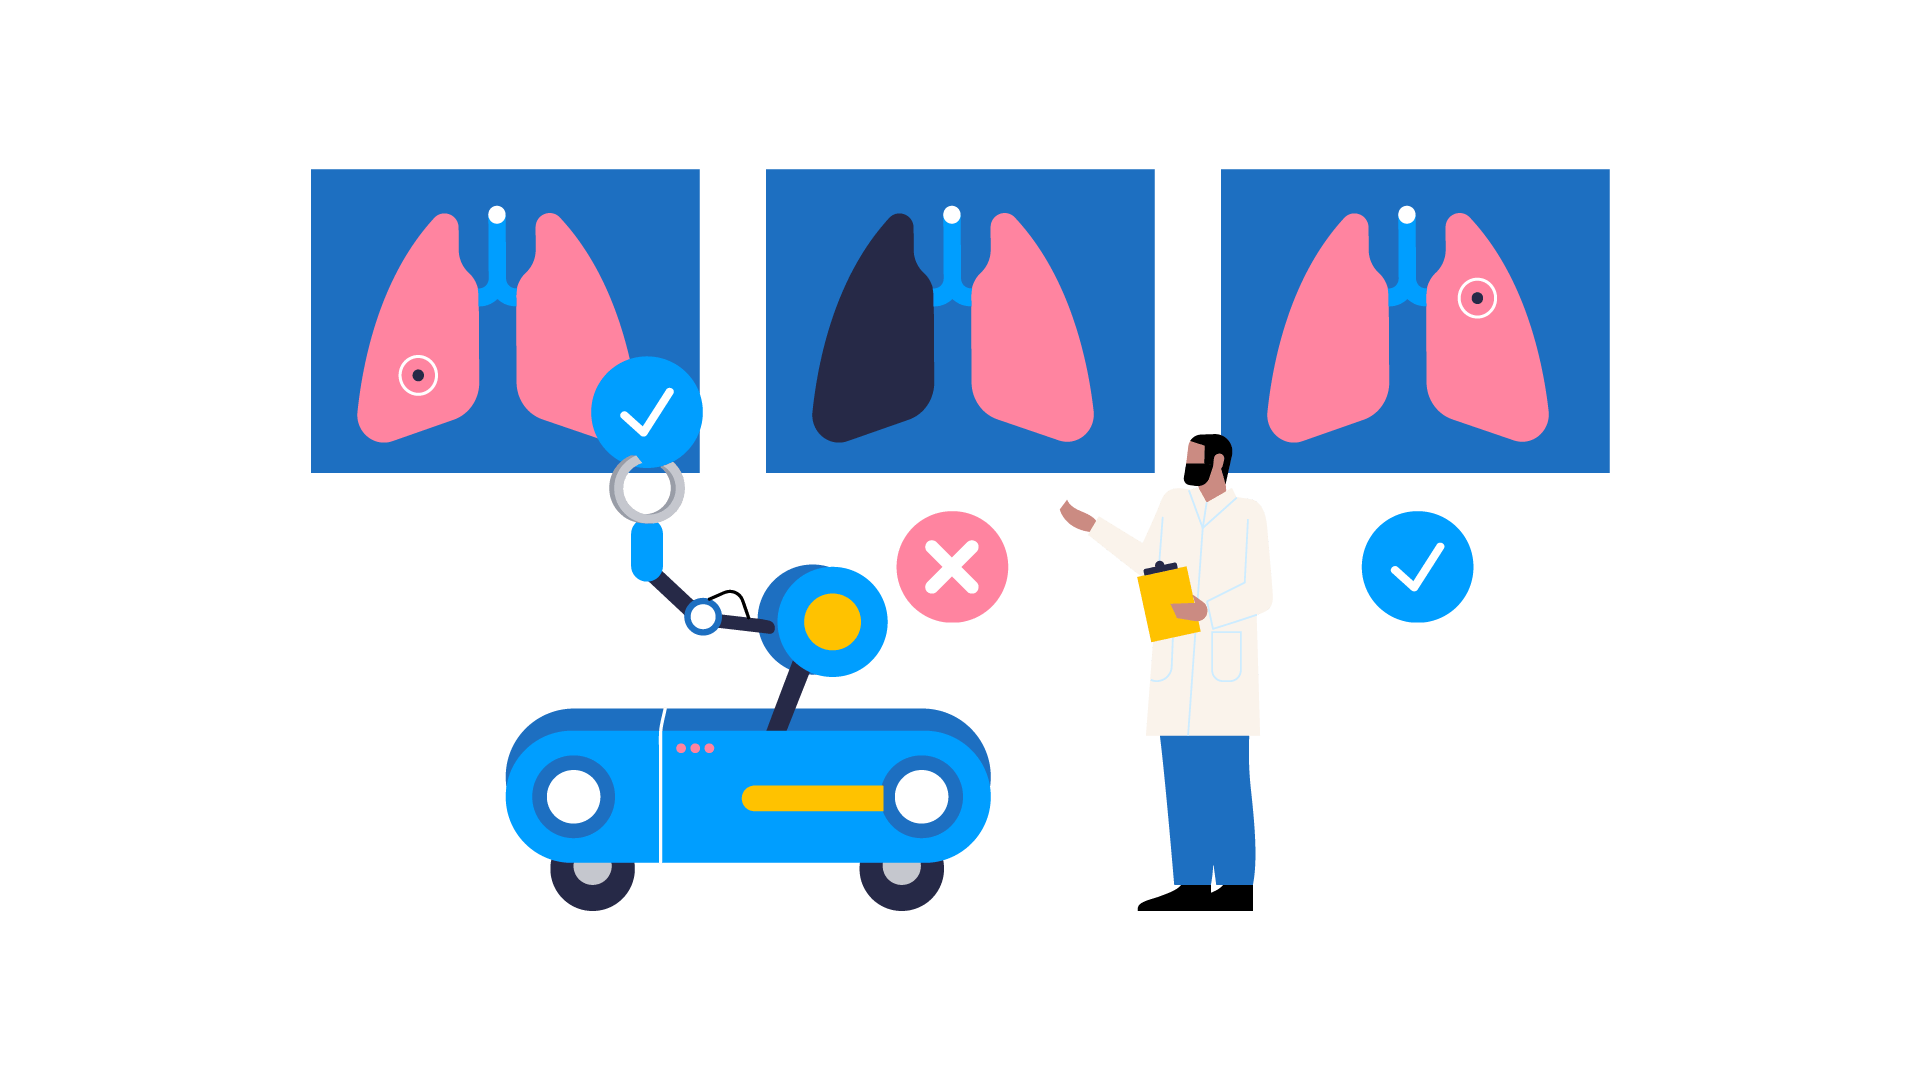
Training an algorithm works similarly. For example, an algorithm might be given a dataset of chest X-rays and told to label each one as healthy or unhealthy. If it's a supervised algorithm, it may start with some help, the dataset might already include labels (such as "pneumonia" or "fracture"), and the algorithm simply needs to review the images repeatedly until it understands why some are healthy and others aren't. If it's unsupervised, it's left to identify the differences itself.
The algorithm makes repeated guesses, and when it gets something wrong, the AI scientist corrects it, much like correcting a child, until it can label all the images in the training dataset accurately and independently.
What are the different stages of the learning process?
There are several key stages:
Error analysis
Patterns such as consistently misclassified examples (e.g., detecting a "fracture" where there isn't one) are investigated to understand why the algorithm is struggling, similar to a child needing a different teaching method for a challenging concept.
Experimentation and fine-tuning
Once the underlying cause is diagnosed, scientists adjust the data or parameters used for training, much like a teacher introducing new approaches or resources to address a learning difficulty.
Regularisation techniques and data augmentation
After repeated training, overfitting can occur as the model becomes too complex and overly specific to its training data. Regularisation techniques reduce these errors by encouraging the model to favour simpler, more generalisable solutions. Data augmentation, such as flipping, rotating, or changing the resolution of images, helps the algorithm understand which factors matter most, increasing the likelihood it can correctly identify something like a fracture on an X-ray. This is similar to how more diverse experiences can enrich a child's understanding of new material.
How is a trained algorithm tested?
Once training is complete, the algorithm is given a different set of images, much like a child being presented with new objects, and tested to see whether it can still label them correctly. This testing process is known as validation. Learning is a dynamic process, involving a continuous cycle of monitoring, analysis, and experimentation to improve performance over time.
What does training involve more formally?
In machine learning specifically, training is the process of teaching an algorithm the correct answer to a specific clinical problem, such as "which of these chest X-ray images show evidence of cancer" or "which of these patients are most at risk of developing type II diabetes."
This process is data-led: the algorithm is given a training dataset from which it learns the correct answer (the target attribute or output). It's crucial that this dataset is of sufficient quantity and quality, otherwise the algorithm's accuracy will be undermined by a "rubbish in, rubbish out" problem.
Exactly how the algorithm learns from the training dataset depends on the type of algorithm involved, whether it's supervised learning, unsupervised learning, zero-shot learning, or reinforcement learning (trial and error).
What happens after training is complete?
Once training is "complete," the algorithm must be validated, shown a separate, unseen subset of the data to check whether it can still perform accurately, and to identify problems such as overfitting or bias. If it passes validation, it must then be evaluated in a real-world setting.
Training data and real-world data are rarely the same quality, particularly in clinical settings. For example, an algorithm trained to recognise cancerous moles via a consumer app will likely have been trained on professional-quality photos taken by a dermatologist in a well-lit setting, not photos taken on someone's phone in a poorly lit living room. It's important to test how these differences in data quality affect the algorithm's overall performance. The algorithm must also be tested for generalisability, otherwise it may fail once taken out of the lab and applied to a broader, real-world population.
Is the train-validate-test process a one-time exercise?
No. This process is often presented as linear, which can create the impression that each step is a one-time, tick-box exercise. In reality, training, validating, and testing an algorithm is recursive, and multiple rounds of training may be needed before the target accuracy level is reached.
Algorithms may also need to be retrained after deployment, either due to changes in the demographic makeup of the population using the algorithm (population drift), or because the algorithm's performance declines over time (model drift).
Curious how these principles are being put into practice?
Owkin is building agentic AI and biological reasoning models to better understand biology and advance biological superintelligence.
K Pro
Owkin's agentic AI co-pilot, applying biological reasoning to real biopharma research and decision-making.